I am a Master’s student in Electronic Information at the University of Science and Technology of China (USTC). I received my B.Eng. in Electronic Information Engineering from Hainan University. From May to November 2026, I was a Research Intern at Ant Group, advised by Yongqi Tong and Wei Wu.
My research focuses on self-evolving LLM agents, i.e., agents that keep improving from their own experience. Specifically, I work on:
- Learning from experience without parameter updates: reflection, skill memory, and credit assignment for agents (REFLEX, NeurIPS 2026).
- Failure diagnosis and recovery: diagnosing why agents fail and repairing them selectively (DARC, KDD 2027).
- Agent skill acquisition at scale: mining verifiable, reusable skills from code (Code2Skill, Hugging Face Daily Papers #3).
- Agent post-training: SFT, preference optimization, and RL (DPO / GRPO) for multimodal agents.
I also have prior experience in computer vision, including image restoration and object detection.
More on my Google Scholar.
🔥 News
- 2026.11: 🎉🎉 Our paper DARC on selective self-correction for LLM agents is accepted to KDD 2027!
- 2026.10: 🔥 PAR ranked #3 on Hugging Face Daily Papers!
- 2026.09: 🔥 Code2Skill ranked #3 on Hugging Face Daily Papers!
- 2026.09: 🎉🎉 Our paper REFLEX on self-evolving agents is accepted to NeurIPS 2026!
- 2026.06: 🎉 CogSENet for blind image deblurring is accepted to ECCV 2026.
- 2026.05: 📄 AtlasVA, teacher-free visual skill memory for VLM agents, is released on arXiv. Our RedNote post got 792 likes & stars!
- 2026.05: 💼 Joined Ant Group as a Research Intern.
- 2026.04: 🏆 Ranked 5th / 223 in the CVPR NTIRE 2026 Image Shadow Removal Challenge.
📝 Publications
* Equal contribution
2027
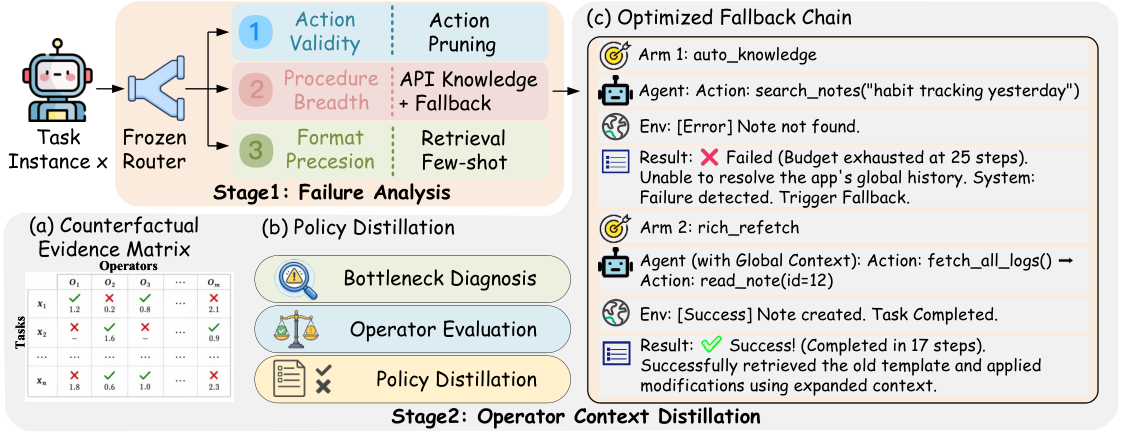
Diagnosis Before Recovery: Turning Agent Failures into Selective Self-Correction
Pan Wang, Yihao Hu, Hang Wang, Zirui Lv, Xin Zhang, Jianshe Li, Jiang-Ming Yang, Wei Wu, Yongqi Tong
arXiv | CCF-A
- A diagnose-before-recover paradigm (Profile → Diagnose → Evaluate → Distill → Freeze) that finds the dominant failure bottlenecks and triggers cost-aware self-correction only when the agent fails.
- Cuts average environment steps by 54.2% and invalid actions by 92.9% on ALFWorld. It also generalizes to AppWorld and XBRL Finance.
2026
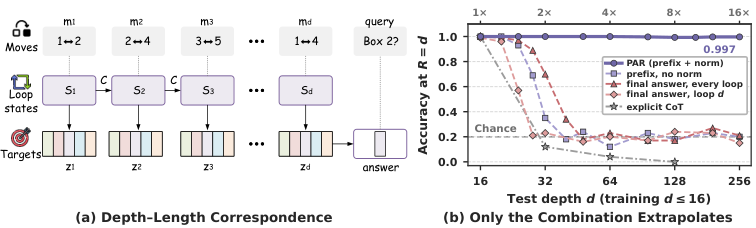
PAR: Progress-Aligned Recurrence for Length Generalization in State Tracking
Pan Wang, Yihao Hu, Guangyuan Dong, Yitong Lin, Hang Wang, Zimi Liu, Zhihao Wen, Jianshe Li, Jiang-Ming Yang, Wei Wu, Yongqi Tong
arXiv | 🤗 Hugging Face Daily Papers #3
- Makes extra recurrent depth in looped LMs useful for longer problems: iteration k is trained to match the state after the first k operations, and recurrent states are norm-anchored.
- On swap-S5, a Qwen2.5-0.5B model trained on ≤32 moves reaches 95.5% full-state accuracy at 512 moves (16× the training length), versus 55.7% for RLT and 0.8% for explicit CoT.
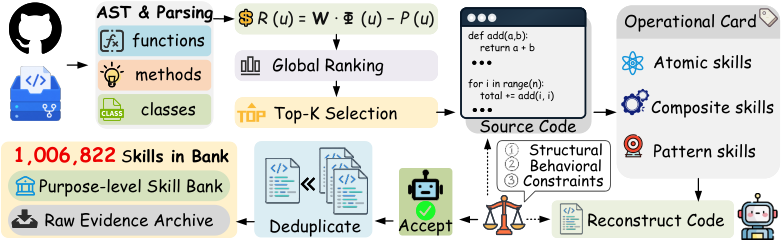
Code2Skill: Grounded Skill Synthesis from Code at Scale for Agentic Intelligence
Yongqi Tong*, Pan Wang*, Hang Wang, Jianshe Li, Xin Zhang, Jiang-Ming Yang, Wei Wu
arXiv | 🤗 Hugging Face Daily Papers #3
- Builds CodeSkillBank: 1,006,822 validated skills mined from 19,769 GitHub repositories.
- Improves agents by 11.7% on average across 72 protocol-matched experiments, covering 9 model configurations and 8 benchmarks.
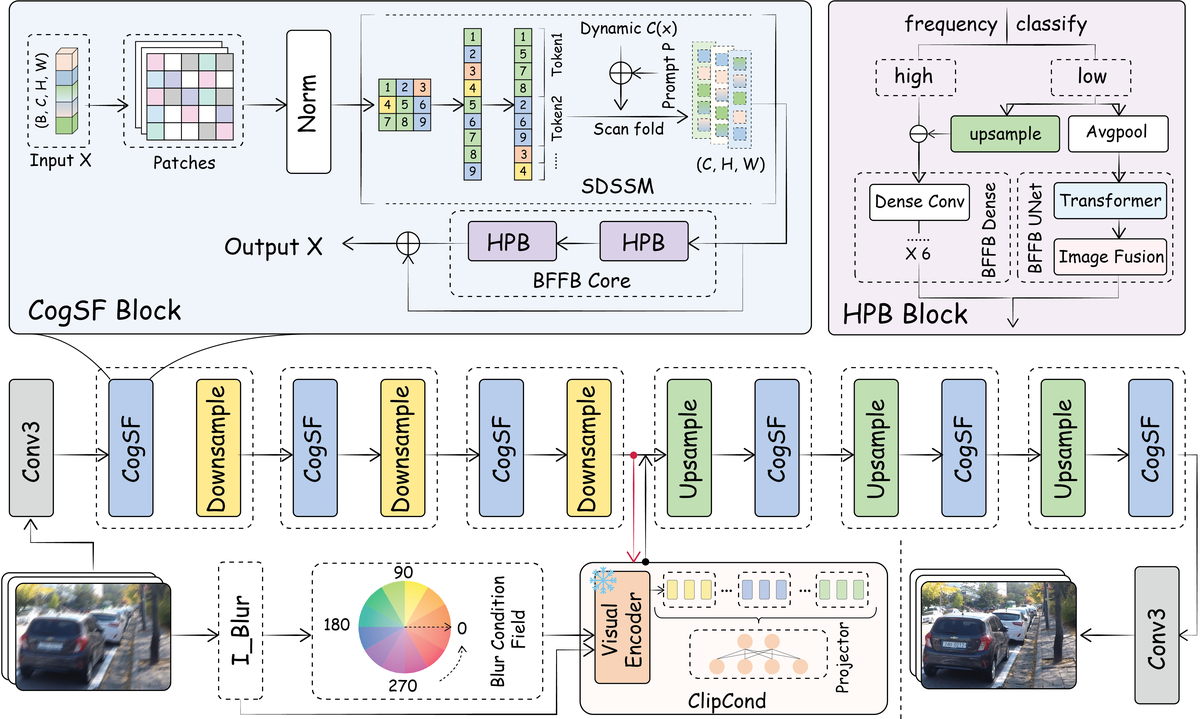
Pan Wang, Yihao Hu, Xiujin Liu
- An eagle-vision-inspired deblurring network. A Semantic-Driven State Space Module regroups tokens by semantics through differentiable routing, and a BiFreqFusionBlock separates high- and low-frequency features with wavelets.
- A continuous Blur Field estimated from the blurry input is fused with CLIP semantic priors, so restoration adapts to spatially non-uniform blur.
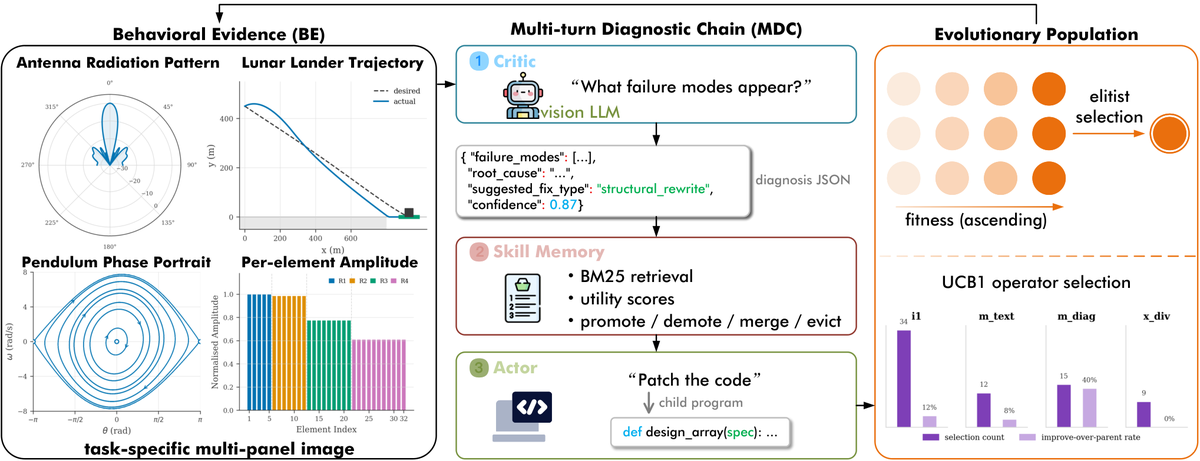
REFLEX: Reflective Evolution from LLM Experience
Pan Wang
arXiv | CCF-A
- A training-free self-evolving agent with a traceable Reflection–Generation–Memory–Credit Assignment loop. A vision-based Critic diagnoses failures, and a self-evolving Skill Memory accumulates, merges, and prunes reusable code skills.
- Under a 100-call budget, it solves Acrobot, Pendulum, and Lunar Lander in a median of 13 / 20 / 24 calls, about half the calls of the baselines. It also cuts the invalid-program rate from 14.7% to 0.6%.
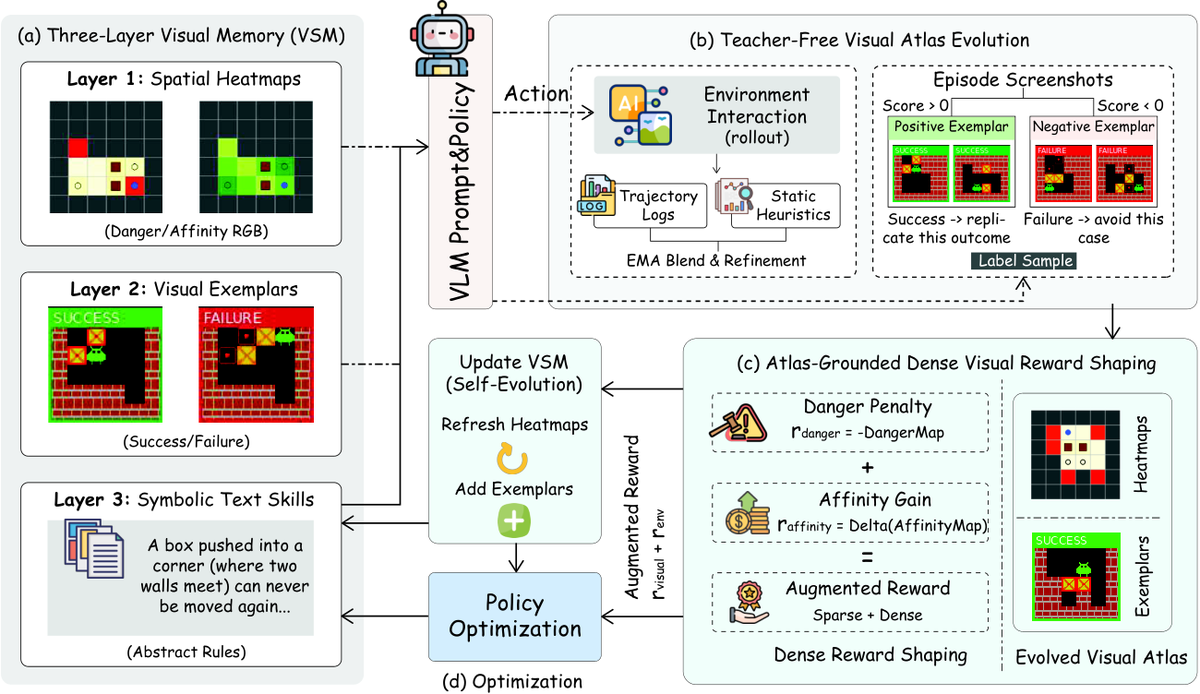
AtlasVA: Self-Evolving Visual Skill Memory for Teacher-Free VLM Agents
Pan Wang, Yihao Hu, Xiujin Liu, Jingchu Yang, Hang Wang, Zhihao Wen
arXiv | Project Page | 📕 RedNote (792 likes & stars)
- Keeps VLM-agent memory visually grounded: a teacher-free, three-layer visual skill memory (spatial heatmaps, visual exemplars, and symbolic text skills) that evolves from trajectory statistics without any external LLM supervision.
- Reuses self-evolving danger/affinity atlases as dense shaping rewards for RL. It outperforms text-centric memory baselines on Sokoban, FrozenLake, 3D embodied navigation, and 3D robotic manipulation.
2025
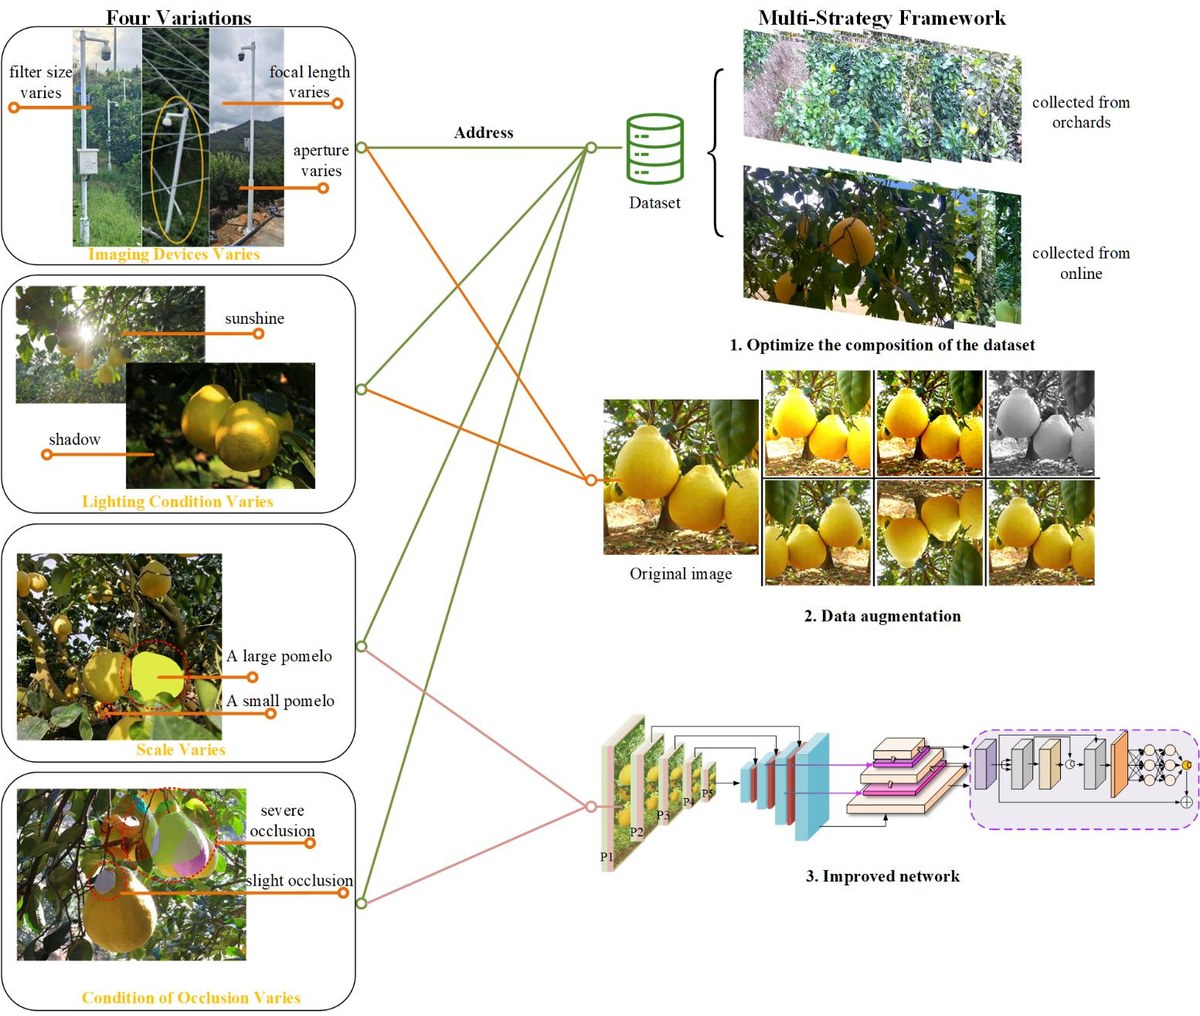
A Multi-Strategy Framework for Enhancing Shatian Pomelo Detection in Real-World Orchards
Pan Wang, Yihao Hu, Xiaodong Bai, Jingchu Yang, Leyi Zhou, Aiping Yang, Xiangxiang Li, Meiping Ding, Jianguo Yao
Journal of Agriculture and Food Research (JCR Q1, IF 7.2)
- A multi-strategy framework for real orchards, which tackles device-dependent tone shifts, unstable lighting, large scale variation, and occlusion. It builds the multi-scenario STP-AgriData dataset and the REAS-Det detector with GSV-Conv.
- Achieves 84.3% mAP@0.50 and 53.6% mAP@0.50:0.95 on STP-AgriData, outperforming recent detectors.
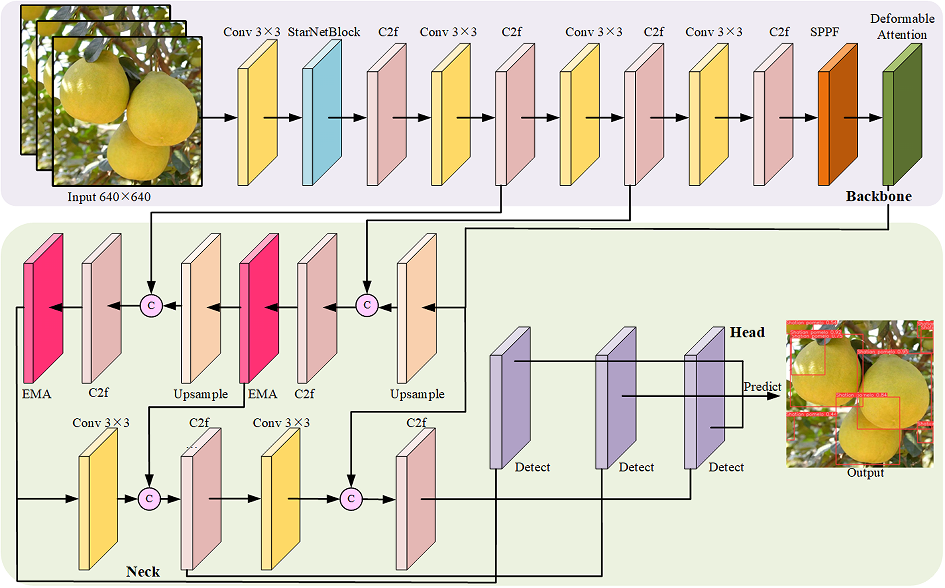
SDE-DET: Precision Detection Network for Shatian Pomelos in Challenging Orchard Environments
Yihao Hu*, Pan Wang*, Xiaodong Bai, Shijie Cai, Hang Wang, Huazhong Liu, Aiping Yang, Xiangxiang Li, Meiping Ding, Hongyan Liu, Jianguo Yao
Smart Agricultural Technology (JCR Q1, IF 7.1)
- A pomelo detector for complex orchards that combines Star Blocks, Deformable Attention for occlusion, and Efficient Multi-Scale Attention for small objects.
- Reaches 0.838 mAP@0.5 (precision 0.883, F1 0.823), outperforming the YOLO series and other mainstream detectors.
Patents
- An Interpretable Image-to-Text Description Method Based on Multi-Model Fusion, Invention Patent, CN202410750467.1, second inventor (supervisor listed first), Granted.
💻 Internships
- 2026.05 - 2026.11, Research Intern, Ant Group, China. Advisors: Yongqi Tong and Wei Wu.
- Million-scale agent skill synthesis: Contributed to the fully automated Code2Skill pipeline, which mined and validated 1,006,822 executable skills from 19,000+ GitHub repositories.
- Failure diagnosis and repair for self-evolving agents: Led DARC, which diagnoses why agents fail and distills cost-aware recovery policies, so that agents can repair themselves and keep evolving. Accepted to KDD 2027.
- Agent–environment co-evolution: Contributed to SEAL, a framework in which agents and their learning environments evolve together, to support scalable agent RL.
- Multimodal agent post-training: Implemented SFT, preference optimization, Offline-DPO, and GRPO for long-horizon visual reasoning and tool use.
🎖 Honors and Awards
- 2026 Excellence Award, UbiComp 2026 CUHK-X Multimodal Human Activity Challenge.
- 2026 Rank 5 / 223, CVPR NTIRE 2026 Image Shadow Removal Challenge.
- 2025 National Second Prize, China Robotics and Artificial Intelligence Competition.
- 2024 National First Prize, National College Student Digital Media Technology Works and Creativity Competition.
- 2024 National Second Prize, Global Campus Artificial Intelligence Algorithm Elite Competition.
- 2024 National Third Prize, National College Student Information Security Competition.
- 2024 National Third Prize, Lanqiao Cup National Software and Information Technology Competition.
- 2023 National First Prize, Global Campus Artificial Intelligence Algorithm Elite Competition.
- 2023 - 2025 National Undergraduate Innovation and Entrepreneurship Training Program: led 1 national-level project and participated in 2 others, all completed.
📖 Educations
- 2026 - now, M.S. in Electronic Information, University of Science and Technology of China (USTC).
- 2022 - 2026, B.Eng. in Electronic Information Engineering, Hainan University.